Been debugging some C++ code. It started off with a program just dying. I narrowed that down to an uncaught exception. I (eventually) narrowed that down to my own code throwing a std::runtime_error. Then much head-scratching ensued, as I was catching it in the catch( ... ) block instead of the catch (std::exception& e) block. I was even more surprised when I could reproduce it in an example that is as minimal as you can get. There is a bug in this code. Give yourself 20 seconds to see if you can spot it before moving on:
#include <iostream>
#include <stdexcept>
int main(int,char**){
try{
throw new std::runtime_error("Hello!");
}catch (std::runtime_error& e){
std::cerr<<"Runtime Error:" << e.what() << "\n";
}catch (std::exception& e){
std::cerr<<"Exception:" << e.what() << "\n";
}catch (...){
std::cerr<<"Unknown Exception\n";
}
return 0;
}
.
.
.
I'll give you a clue: if, like me, you also spend a lot of time in PHP you will find spotting the bug a lot harder.
.
.
.
Yes, it's that new statement. In PHP you throw exceptions with the throw new ErrorClass. If you do that in C++ you are throwing a pointer. Pointers have to be caught as pointers, not as the class they point to. (And, to quote from item 13 in More Effective C++: "Furthermore, catch-by-pointer runs contrary to the conventions established by the language itself.") I knew that, and never intended to throw by pointer; I wish g++ gave a warning for it.
So, to answer the question at the top: my std::runtime_error did not turn into an unknown exception; my std::runtime_error* did !!
Thursday, June 28, 2012


Thursday, June 7, 2012
Push One Git Branch To A Different Server
I have a Github repository, for a library, with two branches on github: master and custom. I then have a third branch, which is application code (including information such as passwords) that I don't want to go on Github. I want to put that 3rd branch on another server.
Before I started my .git/config looked like:
[core]
repositoryformatversion = 0
filemode = true
bare = false
logallrefupdates = true
[remote "upstream"]
url = git@github.com:fennb/phirehose.git
fetch = +refs/heads/*:refs/remotes/upstream/*
[branch "master"]
remote = upstream
merge = refs/heads/master
[remote "origin"]
url = git@github.com:DarrenCook/phirehose.git
fetch = +refs/heads/*:refs/remotes/origin/*
git branch tells me
custom
master
* application
As in my previous article on setting up a remote git repository, I'll assume three machines are involved:
So, first is preparation. On store:
cd /var/git/
mkdir phirehose.git
cd phirehose.git
git init --bare
Next create an alias for it on devel:
git remote add application store:/var/git/phirehose.git/
(Note: "store" is in my ssh config: it is an alias that covers server URL, username, port, etc.)
Then (still on devel machine) I need to type:
git config push.default current
Now check that worked by typing 'git remote -v'
origin git@github.com:DarrenCook/phirehose.git (fetch)
origin git@github.com:DarrenCook/phirehose.git (push)
application store:/var/git/phirehose.git/ (fetch)
application store:/var/git/phirehose.git/ (push)
upstream git@github.com:fennb/phirehose.git (fetch)
upstream git@github.com:fennb/phirehose.git (push)
And in .git/config these lines will have been appended at the end:
[remote "application"]
url = store:/var/git/phirehose.git/
fetch = +refs/heads/*:refs/remotes/application/*
[push]
default = current
Now I can upload the branch with:
git push application
Rush over to 'store' server, and you should see the files in /var/git/phirehose.git/
Now we need to do a quick fix; I'm going to go out on a limb and say this is a git bug. But, anyway, if you look inside the HEAD file you see:
ref: refs/heads/master
But refs/heads/master does not exist! Edit HEAD so it looks like:
ref: refs/heads/application
Now you can go to your 'www' machine and do a "git clone" command.
On your 'www' machine if you type git branch you will see just:
* application
UPDATE:
One last thing. Now you have 2+ remote repositories, on your 'devel' machine, I recommend you type:
git config push.default nothing
This means that git push will no longer work: you always have to specify what you want to push. This is a safety catch to prevent you pushing application to the public GitHub. (I did, and there is no way back, so my only choice was to delete the entire GitHub repository!) So, when I'm in the application branch and I want to push to store I type:
git push application HEAD
See this StackOverflow thread for some background (including a note that default git behaviour might change from 1.7.10+)
Before I started my .git/config looked like:
[core]
repositoryformatversion = 0
filemode = true
bare = false
logallrefupdates = true
[remote "upstream"]
url = git@github.com:fennb/phirehose.git
fetch = +refs/heads/*:refs/remotes/upstream/*
[branch "master"]
remote = upstream
merge = refs/heads/master
[remote "origin"]
url = git@github.com:DarrenCook/phirehose.git
fetch = +refs/heads/*:refs/remotes/origin/*
git branch tells me
custom
master
* application
As in my previous article on setting up a remote git repository, I'll assume three machines are involved:
- devel: where most development is done
- store: the central repository server
- www: the web server, where I want to checkout the branch
So, first is preparation. On store:
cd /var/git/
mkdir phirehose.git
cd phirehose.git
git init --bare
Next create an alias for it on devel:
git remote add application store:/var/git/phirehose.git/
(Note: "store" is in my ssh config: it is an alias that covers server URL, username, port, etc.)
Then (still on devel machine) I need to type:
git config push.default current
Now check that worked by typing 'git remote -v'
origin git@github.com:DarrenCook/phirehose.git (fetch)
origin git@github.com:DarrenCook/phirehose.git (push)
application store:/var/git/phirehose.git/ (fetch)
application store:/var/git/phirehose.git/ (push)
upstream git@github.com:fennb/phirehose.git (fetch)
upstream git@github.com:fennb/phirehose.git (push)
And in .git/config these lines will have been appended at the end:
[remote "application"]
url = store:/var/git/phirehose.git/
fetch = +refs/heads/*:refs/remotes/application/*
[push]
default = current
Now I can upload the branch with:
git push application
Rush over to 'store' server, and you should see the files in /var/git/phirehose.git/
Now we need to do a quick fix; I'm going to go out on a limb and say this is a git bug. But, anyway, if you look inside the HEAD file you see:
ref: refs/heads/master
But refs/heads/master does not exist! Edit HEAD so it looks like:
ref: refs/heads/application
Now you can go to your 'www' machine and do a "git clone" command.
On your 'www' machine if you type git branch you will see just:
* application
UPDATE:
One last thing. Now you have 2+ remote repositories, on your 'devel' machine, I recommend you type:
git config push.default nothing
This means that git push will no longer work: you always have to specify what you want to push. This is a safety catch to prevent you pushing application to the public GitHub. (I did, and there is no way back, so my only choice was to delete the entire GitHub repository!) So, when I'm in the application branch and I want to push to store I type:
git push application HEAD
See this StackOverflow thread for some background (including a note that default git behaviour might change from 1.7.10+)
Monday, May 28, 2012
php-webdriver bindings for selenium: how to add time-outs
Not all webpages finish loading. In particular I've a page that keeps streaming data back to the client, and never finishes. (For instance it might be used from an ajax call.) I want to test this from Selenium, but have been hitting problems. The main problem is Selenium's get() function, which is used to fetch a fresh URL, does not return until the page has finished loading [1]. In my case that meant never, and so my test script locked up!
However all is not lost; you can specify a page load timeout. It is hidden in the protocol docs, but I've added it to the php webdriver library I use (v0.9). See the three functions below [2]; just paste them in to the bottom of WebDriver.php.
I also needed one bug fix in WebDriver.php's public function get($url). It currently ends with:
$response=curl_exec($session);
Just after that line you should add this:
return $this->extractValueFromJsonResponse($response);
The time-out, and that bug fix, can be used like this:
require_once "/usr/local/src/selenium/php-webdriver-bindings-0.9.0/phpwebdriver/WebDriver.php";
$webdriver = new WebDriver("localhost", "4444");
$webdriver->connect("firefox");
$webdriver->setPageLoadTimeout(2000); //2 seconds
$url="http://example.com/forever.php"; //A page that never finishes loading
$obj=$webdriver->get($url);
if($obj===null){
$current_url=$webdriver->getCurrentUrl();
if(!$current_url){
//Selenium-server not running
}
else{
//It worked! (it completed loading in under two seconds)
}
}
elseif($obj->class=='org.openqa.selenium.TimeoutException'){
//It timed out
}
elseif($obj->class=='org.openqa.selenium.remote.UnreachableBrowserException'){
//Browser was closed (or selenium-server was shutdown)
}
else{
echo "FAILED:";print_r($obj);
}
This is useful stuff. There is still one problem left for me: I wanted to load two seconds worth of data and then look at it. But I cannot. The browser refuses to listen to selenium while it is loading a page! So though get() returned control to my script after two seconds, I cannot do anything with that control (except close the browser window), because the URL is still actually loading. And it will do that forever!! (I've played with an interesting alternative approach, which also fails, but suggests that a solution is possible. But that is out of the scope of this post, which is to show how to add the time limit functions to php-webdriver-bindings.)
[1]: This is browser-specific behaviour, not by Selenium design. Firefox and Chrome, at least, behave this way.
[2]: Consider this code released, with no warranty, under the MIT license, and permission granted to use in the php-webdriver-bindings project with no attribution required.
/**
* Set wait for a page to load.
*
* This timeout is for the get() function. (Firefox and Chrome, at least, won't return from get()
* until a page is fully loaded. If remote server is streaming content, they would never return
* without this time-out.)
*
* @param Number $timeout Number of milliseconds to wait.
* @author Darren Cook, 2012
* @internal http://code.google.com/p/selenium/wiki/JsonWireProtocol#/session/:sessionId/timeouts
*/
public function setPageLoadTimeout($timeout) {
$request = $this->requestURL . "/timeouts";
$session = $this->curlInit($request);
$args = array('type'=>'page load', 'ms' => $timeout);
$jsonData = json_encode($args);
$this->preparePOST($session, $jsonData);
curl_exec($session);
}
/**
* Set wait for a script to finish.
*
* @param Number $timeout Number of milliseconds to wait.
* @author Darren Cook, 2012
* @internal http://code.google.com/p/selenium/wiki/JsonWireProtocol#/session/:sessionId/timeouts
*/
public function setAsyncScriptTimeout($timeout) {
$request = $this->requestURL . "/timeouts";
$session = $this->curlInit($request);
$args = array('type'=>'script', 'ms' => $timeout);
$jsonData = json_encode($args);
$this->preparePOST($session, $jsonData);
curl_exec($session);
}
/**
* Set implict wait.
*
* This is for waiting for page elements to appear. Not useful for scripts or
* waiting for the initial get() call to time out.
*
* @param Number $timeout Number of milliseconds to wait.
* @author Darren Cook, 2012
* @internal http://code.google.com/p/selenium/wiki/JsonWireProtocol#/session/:sessionId/timeouts
*/
public function setImplicitWaitTimeout($timeout) {
$request = $this->requestURL . "/timeouts";
$session = $this->curlInit($request);
$args = array('type'=>'implicit', 'ms' => $timeout);
$jsonData = json_encode($args);
$this->preparePOST($session, $jsonData);
curl_exec($session);
}
However all is not lost; you can specify a page load timeout. It is hidden in the protocol docs, but I've added it to the php webdriver library I use (v0.9). See the three functions below [2]; just paste them in to the bottom of WebDriver.php.
I also needed one bug fix in WebDriver.php's public function get($url). It currently ends with:
$response=curl_exec($session);
Just after that line you should add this:
return $this->extractValueFromJsonResponse($response);
The time-out, and that bug fix, can be used like this:
require_once "/usr/local/src/selenium/php-webdriver-bindings-0.9.0/phpwebdriver/WebDriver.php";
$webdriver = new WebDriver("localhost", "4444");
$webdriver->connect("firefox");
$webdriver->setPageLoadTimeout(2000); //2 seconds
$url="http://example.com/forever.php"; //A page that never finishes loading
$obj=$webdriver->get($url);
if($obj===null){
$current_url=$webdriver->getCurrentUrl();
if(!$current_url){
//Selenium-server not running
}
else{
//It worked! (it completed loading in under two seconds)
}
}
elseif($obj->class=='org.openqa.selenium.TimeoutException'){
//It timed out
}
elseif($obj->class=='org.openqa.selenium.remote.UnreachableBrowserException'){
//Browser was closed (or selenium-server was shutdown)
}
else{
echo "FAILED:";print_r($obj);
}
This is useful stuff. There is still one problem left for me: I wanted to load two seconds worth of data and then look at it. But I cannot. The browser refuses to listen to selenium while it is loading a page! So though get() returned control to my script after two seconds, I cannot do anything with that control (except close the browser window), because the URL is still actually loading. And it will do that forever!! (I've played with an interesting alternative approach, which also fails, but suggests that a solution is possible. But that is out of the scope of this post, which is to show how to add the time limit functions to php-webdriver-bindings.)
[1]: This is browser-specific behaviour, not by Selenium design. Firefox and Chrome, at least, behave this way.
[2]: Consider this code released, with no warranty, under the MIT license, and permission granted to use in the php-webdriver-bindings project with no attribution required.
/**
* Set wait for a page to load.
*
* This timeout is for the get() function. (Firefox and Chrome, at least, won't return from get()
* until a page is fully loaded. If remote server is streaming content, they would never return
* without this time-out.)
*
* @param Number $timeout Number of milliseconds to wait.
* @author Darren Cook, 2012
* @internal http://code.google.com/p/selenium/wiki/JsonWireProtocol#/session/:sessionId/timeouts
*/
public function setPageLoadTimeout($timeout) {
$request = $this->requestURL . "/timeouts";
$session = $this->curlInit($request);
$args = array('type'=>'page load', 'ms' => $timeout);
$jsonData = json_encode($args);
$this->preparePOST($session, $jsonData);
curl_exec($session);
}
/**
* Set wait for a script to finish.
*
* @param Number $timeout Number of milliseconds to wait.
* @author Darren Cook, 2012
* @internal http://code.google.com/p/selenium/wiki/JsonWireProtocol#/session/:sessionId/timeouts
*/
public function setAsyncScriptTimeout($timeout) {
$request = $this->requestURL . "/timeouts";
$session = $this->curlInit($request);
$args = array('type'=>'script', 'ms' => $timeout);
$jsonData = json_encode($args);
$this->preparePOST($session, $jsonData);
curl_exec($session);
}
/**
* Set implict wait.
*
* This is for waiting for page elements to appear. Not useful for scripts or
* waiting for the initial get() call to time out.
*
* @param Number $timeout Number of milliseconds to wait.
* @author Darren Cook, 2012
* @internal http://code.google.com/p/selenium/wiki/JsonWireProtocol#/session/:sessionId/timeouts
*/
public function setImplicitWaitTimeout($timeout) {
$request = $this->requestURL . "/timeouts";
$session = $this->curlInit($request);
$args = array('type'=>'implicit', 'ms' => $timeout);
$jsonData = json_encode($args);
$this->preparePOST($session, $jsonData);
curl_exec($session);
}
Friday, May 18, 2012
EC2 and Windows: a match made in... Hell
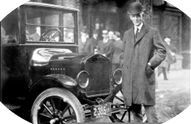 Henry Ford is famous for his lack of flexibility over the Model T: You can it in any colour you want, as long as it is black.
I think Amazon have taken a leaf out if his book, when offering their Windows instances: You can have any size disk you want, as long as it is 30Gb.
Don't believe me? Go on, try automating the creation of a 100Gb boot disk Windows machine. Or creating one from the web interface, without any post-configuration steps in Windows itself.
(I'll save you the Google: here is the AWS engineers telling you the multiple steps needed to achieve that. The instructions are different depending on the exact version of Windows.)
In fact, try automating anything to do with Windows configuration, using EC2. You can't. It can't be, won't be, scripted. You always have to log on afterwards (going through the EC2 Console to get your almost-impossible-to-type password) to do something. Usually quite a tedious and time-consuming something.
The bottom-line: Windows is not designed for the cloud.
...and yet, some of my clients, and some of my potential clients, insist on trying to use Windows anyway. The cloud is where they feel they should be, so people want to move their legacy apps there. Whenever I ask them how they do it, or why they do it, they seem to find justification. It is the cloud, look we're scaling. We're faster. It works! Like a man let out of prison, and running free in the meadow... only he still has the manacles and chains from his time doing time. Am I carrying my metaphor too far by wishing people would stop and take the Linux axe to the manacles before rushing off to the meadow?
Are you an expert at automating Windows on EC2? Please post a comment showing off your knowledge. I'm willing to learn, and will edit this article if you convince me it can be done :-)
Subscribe to:
Posts (Atom)